Apple в Китае: как одна цепь поставок изменила геополитику

Есть книги, которые объясняют событие. И есть книги, которые объясняют систему, породившую это событие. «Apple in China» Патрика МакГи — из второй категории. Журналист Financial Times провёл четыре года, работая над расследованием, основанным на более чем 200 интервью с людьми внутри и вокруг Apple — инженерами, менеджерами, поставщиками, чиновниками. Результат — бестселлер New York Times, который читается одновременно как история бизнеса, геополитический анализ и предупреждение.

Интервью #208 подкаста Alcott Global с МакГи — один из немногих разговоров, где тема цепи поставок рассматривается не изнутри компании, а снаружи: глазами журналиста, который видел документы, которые корпорации предпочли бы не показывать.

Как Apple случайно стала архитектором китайского технологического чуда

Apple не ставила задачу развить китайскую промышленность. Apple ставила задачу производить продукты с точностью и в масштабе, недостижимом где-либо ещё. Китай оказался единственным местом, где это возможно.

Масштаб сотрудничества поражает даже тех, кто знаком с темой. МакГи приводит цифру: $55 млрд в год — текущие операционные расходы Apple, связанные с Китаем. Это не инвестиции в страну. Это стоимость содержания производственной экосистемы, которая за двадцать лет выросла в нечто, не имеющее аналогов в мировой промышленной истории.

МакГи называет Apple «крупнейшим частным вкладчиком в технологический подъём Китая» — и подкрепляет это тезисом о том, что объём инвестиций Apple превысил и план Маршалла, и американский закон о полупроводниках CHIPS Act. Разница в том, что Apple инвестировала не в инфраструктуру и не в безопасность — она инвестировала в производственную компетенцию, которую невозможно экспортировать обратно.

«Эффект роя»: непреднамеренная передача знаний

Когда Apple в начале 2000-х выбрала Foxconn в качестве основного производственного партнёра, она столкнулась с проблемой: стандарты качества Apple и операционные возможности китайских заводов находились в разных мирах. Решение было прагматичным — отправить собственных инженеров прямо на производственные линии Shenzhen.

Сотни, потом тысячи инженеров Apple работали бок о бок с китайскими коллегами. Они передавали не просто процедуры — они передавали способ мышления о точности, о допусках, о системе контроля качества. МакГи называет это «эффектом роя»: Apple буквально засевала заводы своими людьми.

Это решение изменило китайскую промышленность. Инженеры, обученные на стандартах Apple, уходили создавать собственные компании или переходили к конкурентам. Экосистема поставщиков компонентов — тысячи компаний, многие из которых стали мировыми лидерами в своих нишах, — выросла вокруг заказов Apple и благодаря её требованиям. Shenzhen стал тем, чем он является сегодня, во многом потому что Apple решила там производить iPhone.

Foxconn как геополитический посредник

Отношения Apple с Foxconn — это не просто контракт производителя и заказчика. Это была система управления политическими рисками.

Foxconn к 2010-м годам присутствовал в 20+ китайских провинциях и нанимал более миллиона человек. Это делало его субъектом, с которым китайское правительство не могло не считаться. Apple пользовалась этим щитом: проблемы в отношениях с Пекином решались через Foxconn, а не напрямую. Тим Кук выстраивал отношения с американскими президентами и китайскими руководителями поочерёдно — балансируя между двумя геополитическими центрами с хирургической точностью.

Этот механизм дал сбой в 2013 году. CCTV — китайское государственное телевидение — выпустило в прайм-тайм многочасовую атаку на Apple, обвиняя компанию в дискриминационной политике гарантийного обслуживания. Атака была организована: одновременно публикации появились в десятках изданий. МакГи интерпретирует это как сигнал: Китай давал понять, что Apple больше не может считать своё присутствие в стране политически защищённым.

Apple отреагировала публичными извинениями от Тима Кука — беспрецедентным шагом для компании, никогда публично не уступавшей давлению. Это был разворотный момент, после которого отношения превратились из партнёрства в сложную взаимную зависимость.

Почему выход из Китая структурно невозможен

После 2016 года — и особенно после 2019-го, когда торговая война между США и Китаем вышла в открытую фазу, — Apple начала заявлять о диверсификации. Индия. Вьетнам. «Деглобализация». «Чайна+1».

МакГи разбирает эту риторику без сентиментальности.

Проблема не в контрактах и не в политической воле руководства. Проблема в том, что за двадцать лет Китай накопил производственную экосистему, которую невозможно воспроизвести в любом другом месте за обозримое время. Сотни поставщиков компонентов сосредоточены в радиусе нескольких часов езды от заводов Foxconn. Инженерная экспертиза — там. Инфраструктура прецизионного производства — там. Скорость прототипирования нового продукта от идеи до рабочего образца — там.

Foxconn обслуживает не только Apple — это многоклиентная модель, которая позволяет распределять постоянные затраты и поддерживать загрузку мощностей. Это делает юнит-экономику производства в Китае принципиально иной, чем где-либо ещё. Индия может воспроизвести масштаб. Вьетнам — логистику. Ни одна страна не воспроизведёт плотность экосистемы за 5–10 лет.

МакГи не говорит, что диверсификация невозможна. Он говорит, что Apple сама загнала себя в угол: каждый год роста продаж означал более глубокую интеграцию с китайской производственной базой, которая делала следующий год роста возможным. Выход стоит не денег — выход стоит нескольких поколений товаров.

Производство как государственная стратегия

Возможно, самый важный тезис книги МакГи — и его же вывод в разговоре с Раду Паламарью — касается природы производственной политики в Китае.

Для западного бизнеса производство — это часть экономики. Для Китая производство — это государственная идентичность и инструмент геополитической власти. Политика «Made in China 2025», последовательное субсидирование производственных компетенций в стратегических отраслях, отказ рассматривать деиндустриализацию как допустимый исход — всё это части одной стратегии, в которой суверенитет над производственными процессами понимается как форма суверенитета как такового.

Apple строила цепь поставок, оптимизируя юнит-экономику каждого следующего iPhone. Китай строил промышленную мощь, используя Apple как инструмент этого строительства. Обе стороны получили то, чего хотели — на какое-то время. Теперь они обнаружили, что настолько переплетены, что развязка будет болезненной для обеих.

Что это означает для тех, кто строит глобальные цепи поставок

Книга МакГи — не о технологических компаниях. Она о том, что происходит, когда стратегические решения по цепи поставок принимаются без учёта их долгосрочных геополитических последствий.

Концентрация производства в одном регионе ради операционной эффективности создаёт зависимость, которая через десять лет выглядит как структурная уязвимость. Передача компетенций поставщикам ради масштаба создаёт конкурентов, которых не было, когда решение принималось. Использование политических посредников для управления отношениями с государством работает — до тех пор, пока государство не решает, что посредник больше не нужен.

Ни одно из этих решений не было ошибкой в момент принятия. Все они стали проблемой в результате накопления.

Apple — крайний случай по масштабу. Но логика та же самая, что применима к любой компании, выстраивающей глобальную цепь поставок в мире, где геополитика снова стала операционной переменной.
Рубрика: Управление рисками | Оставить комментарий

Forecasting Demand That Swings With the Weather

Your demand is not random. It is reading the weather forecast

Picture a weekly supply review in late June. Last week a heatwave pushed one region above 30 °C for five days. Cold-beverage bases and dessert mixes ran out in a third of the outlets served by one cross-dock hub. The stock existed in the network, just not where the heat was.

The planner shows the forecast: a four-week average of the same weekday, the default setting in the replenishment system. It predicted a normal July week.

Someone asks the obvious question: “Couldn’t we have seen this coming? The heatwave was on every weather app for a week.”

The usual answer is “summer demand is volatile”, followed by a request for more safety stock. More stock is the expensive answer. You pay for it all season, it fills chilled space, and for short-life products it ends up written off when the weather turns.

The better question is this: how much of that “volatility” is explained by something we can see days in advance, and what is it worth to use it?

Noise is what you cannot explain

A swing in demand that follows the temperature on the same day is not noise. It is a variable you left out of the model.

That distinction matters for money. Safety stock is supposed to protect you against uncertainty. When you hold it against a swing you could have predicted, you are not paying for uncertainty. You are paying for ignorance.

For cold beverages, desserts and other temperature-sensitive lines, the weather is the single largest driver of day-to-day demand. Yet in most restaurant networks, these categories are still forecast as if the weather did not exist.

The Asymmetry That a Single Slope Misses

Even teams that do use temperature usually add it as one slope: “sales rise x% per degree.”

That fails because the response is not symmetric. Analysis of beverage sales across climate zones shows a clear pattern:

  • Above the threshold: +12–13% demand per degree — heat triggers thirst-driven, impulsive purchases with no natural ceiling.
  • Below the threshold: −5–6% demand per degree — cold mostly removes casual traffic and leaves loyal core demand alone.

A single slope averages these two regimes. It ends up too steep in winter and too flat in summer, which means it under-forecasts exactly the days that cause stock-outs.

The Model: A Hinge, in Logs

The fix is a regression with a bend in it. Model the logarithm of daily demand:

ln(y) = α + β_hot × max(T − τ, 0) − β_cold × max(τ − T, 0)
+ weekday effects + γ × promo + trend + ε

Where:

  • y is daily demand for one product at one cluster of outlets
  • T is the daily mean temperature (for forecasting: the weather forecast, not the actual)
  • τ is the threshold where behaviour changes regime
  • β_hot and β_cold are the slopes above and below the threshold
  • γ is the promotion lift; ε is the noise we cannot explain

Working in logs does two useful things. Effects multiply, as they do in reality: a hot Saturday with a promotion is “hot × Saturday × promotion”, not a sum. And every coefficient reads directly as a percentage — a β_hot of 0.12 means e^0.12 = 1.127, so +12.7% per degree.

For a given threshold, this is ordinary least squares. The threshold itself is found by brute force: fit the model for every candidate from 10 °C to 28 °C in half-degree steps and keep the one with the lowest error or lowest AIC. If the hinge does not beat a single slope, your category does not have the asymmetry — and you have learned something too.

A Worked Example

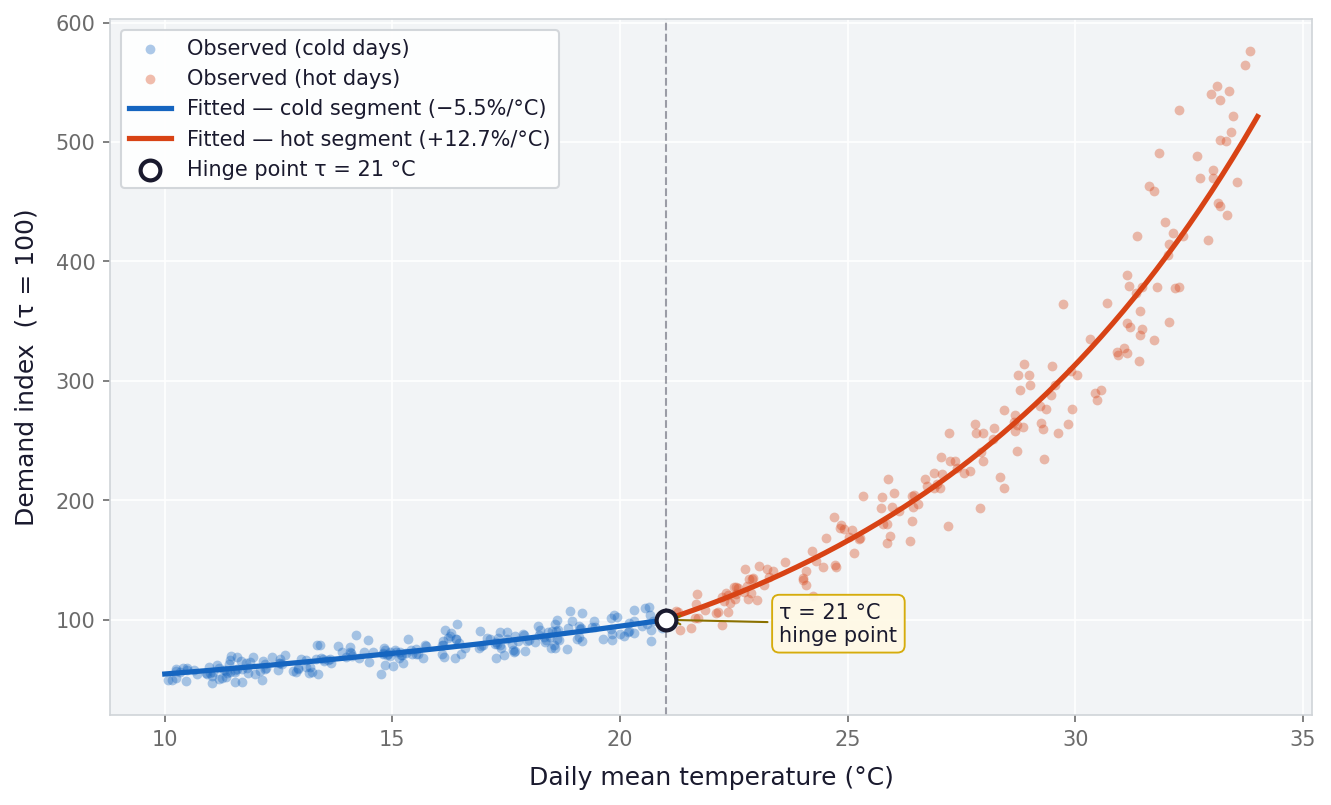
To make this concrete, I simulated two years of daily data for one hub of a restaurant network: about 70 outlets in a temperate climate, one cold-beverage base sold in cases. The data are calibrated to a real-world QSR network structure, with a threshold of 21 °C, +12.7% per degree above, −5.5% per degree below, weekday effects, promotions and a 3% annual trend. In July of year two there is a twelve-day heatwave peaking at 32.4 °C, hotter than any day in year one.

Setup: fit on year one, test on year two; daily review, 5-day lead time (6-day exposure window); 99.3% service target (z = 2.44); $25 per case, 25% annual holding rate. Weather forecast error: 1.5 °C one day ahead, rising to 3.0 °C six days ahead.

What the model recovered from one year of data:

  • Threshold: 20.5 °C (true: 21 °C)
  • Above threshold: +12.6% per degree (true: +12.7%)
  • Below threshold: −5.6% per degree (true: −5.5%)
  • Explained variance in log demand: 97.7%
Daily demand index vs mean temperature with hinge regression fit
Figure 1. Daily demand index vs mean temperature. Each dot is one day. Two OLS segments meet at the fitted hinge τ = 20.5 °C (true: 21 °C). R² in log demand = 97.7%

Then I compared day-ahead forecasts on year two against what replenishment systems typically use, and against gradient boosting on the same inputs.

Out-of-sample forecast accuracy: hinge regression vs gradient boosting vs baselines
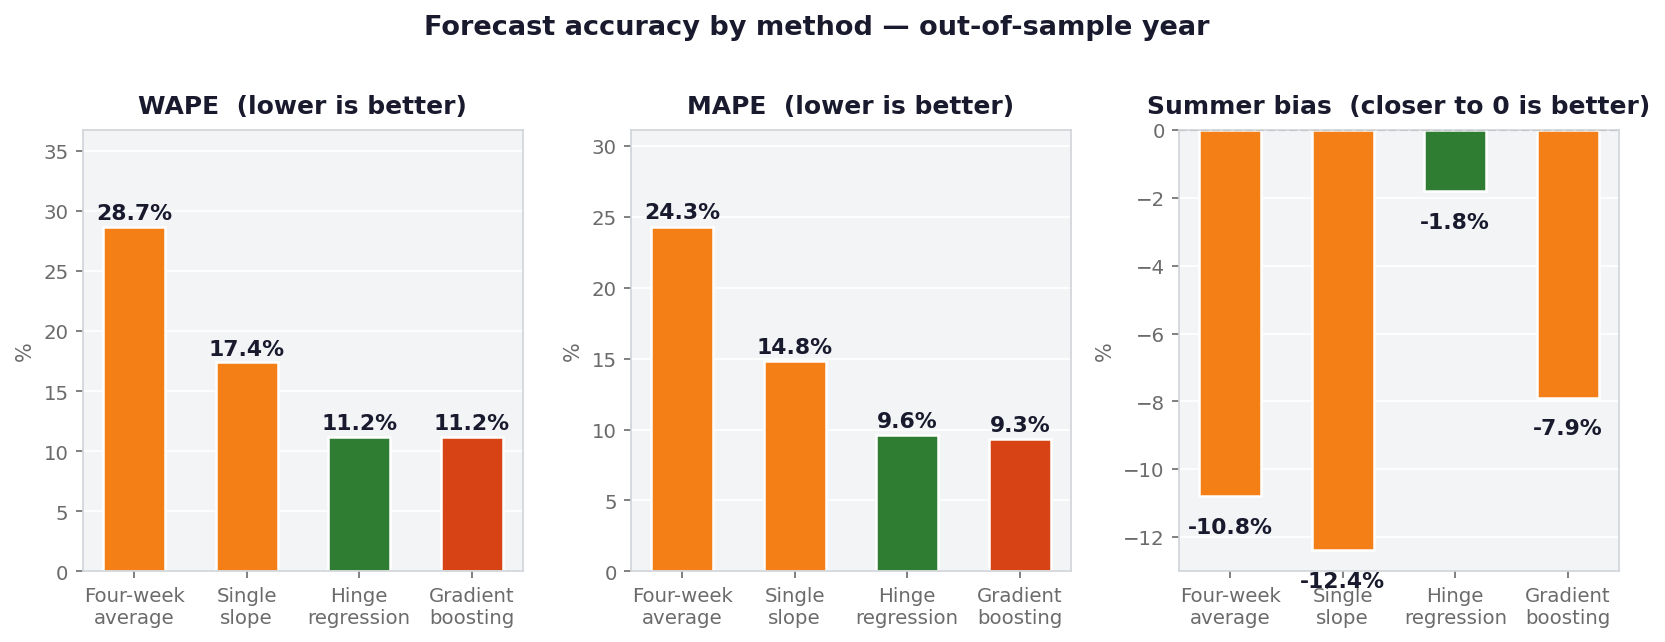
Figure 2. Out-of-sample forecast accuracy — year two. Summer bias is the mean error for June–August. Hinge regression matches gradient boosting on WAPE while cutting summer bias to −1.8%.

Three things stand out.

The default is worse than doing nothing clever. The four-week same-weekday average has a WAPE of 28.7%. Simply copying yesterday’s demand gives 15.1%. In a weather-driven category, last month is the wrong reference. Its annual bias looks harmless only because it lags in both directions: −10.8% as spring warms up, +5.8% in winter.

The single slope looks fine on MAPE and fails in summer. It under-forecasts June to August by 12.4% — exactly the asymmetry, ignored.

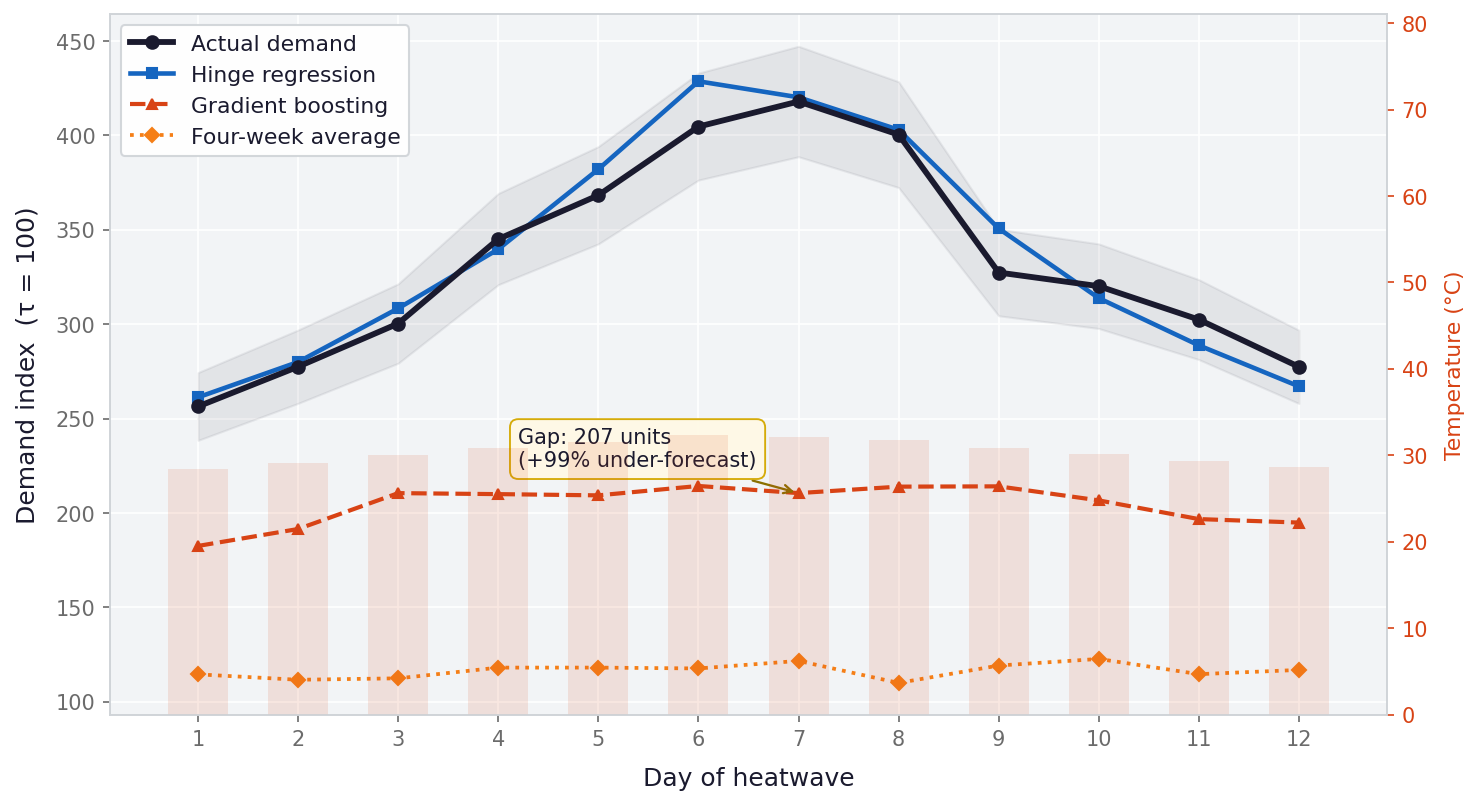
Machine learning ties on accuracy and loses on bias. Tuned gradient boosting matches the hinge model on WAPE (11.2%) and even edges it on MAPE. On a standard dashboard, it wins. But it under-forecasts summer by 7.9% and the heatwave by 14.5%. The reason is structural: a tree model predicts a constant beyond the hottest day in its training data. The hottest day in year one was 30.2 °C. The heatwave reached 32.4 °C. The model flattened exactly when demand accelerated.

Heatwave forecast vs actual demand
Figure 3. Twelve-day heatwave — forecast vs actual demand. Orange bars show temperature. The hinge model tracks the peak; gradient boosting flattens above its training maximum of 30.2 °C.

Why Bias Matters More Than MAPE

MAPE and WAPE tell you how big your errors are. Safety stock can absorb errors of a known size. What it cannot absorb is a forecast that is consistently on one side.

In the example, gradient boosting needs a summer buffer of 381 cases. But its −7.5% bias over the six-day window quietly eats 73 of them. Effective cycle service falls from the 99.3% target to about 97.6% — in the season when stock-outs are most visible.

Report bias next to MAPE. Report it by month and by temperature band. A forecast that is 10% wrong in both directions is a safety-stock problem. A forecast that is 5% wrong but always low is a service problem.

From Forecast Error to Working Capital

The safety-stock formula is the familiar one:

SS = z × σ(R+L) ≈ z × σ_d × √(R + L)

Where z is the safety factor, R the review interval, L the lead time, σ_d the standard deviation of daily forecast error.

Two lessons from the example.

First, σ is seasonal. For the hinge model, the summer error is about five times the winter error in cases. A safety stock calibrated on the annual σ would deliver only about 92% service in summer and hold 2.9 times the stock needed in winter. Temperature-sensitive items need season-specific safety-stock tables.

Second, the √(R+L) shortcut understates weather-driven risk. Weather forecast errors get worse with horizon and persist from day to day. Measured directly over the six-day window, the hinge model’s summer σ is 41% higher than √6 times its daily σ. For the four-week average it is 2.2× higher. Measure σ over the full window instead of scaling it.

With that done, moving this SKU at this hub from the four-week average to the hinge model cuts the average safety stock from 334 to 127 cases. In summer the buffer drops from 7.8 days of demand to 1.8 days — about $5,175 of working capital for one SKU at one hub.

Scale it to four temperature-sensitive SKUs at 17 hubs: ~$352,000 released, ~$88,000 a year in holding cost, before counting chilled space and write-offs. Service goes up, not down.

The Weather Forecast Is Now Your Biggest Error

Once the model is in place, the largest remaining source of error in summer is not customer behaviour. It is the weather forecast.

With perfect temperature knowledge, the summer six-day σ would fall from 117 to 40 cases. Weather-forecast error accounts for about 88% of the summer error variance. At 12.6% per degree, a forecast that is 2.5 °C too hot inflates the demand forecast by about 35%.

Practical implications:

  • Track your weather forecast error per location and per horizon, as carefully as your demand forecast error.
  • Archive the forecasts as issued, not only the actual temperatures. Most teams keep only actuals and cannot fit on what they really knew.
  • Know what a better weather source is worth. In the example, moving from a 1.5–3.0 °C error to a 1.0–2.0 °C error saves about $63,000 of working capital across 68 SKU-hubs.

A technical note: because the hot side is convex, a noisy weather forecast biases demand upward. With a 3 °C error, that bias is about 6.7% on hot days. Fitting the model on forecasts as issued fixes most of it.

When to Use Machine Learning

This is not an argument against gradient boosting. Use it when there are many interacting drivers — temperature, humidity, holidays, local events, delivery-app outages — and enough pooled history to learn them. When you do, constrain it to be monotonic in temperature, and feed it features that extrapolate, such as the hinge terms themselves.

Use a regression when the drivers are few, the shape is known, the business needs coefficients it can read (“+12.6% per degree”), and the forecast must work outside the range of history. A record heatwave is always outside the range of history.

One warning on flexibility: the deep-tree version in the test reproduced the training year almost perfectly and was worse on the test year than the tuned version. A model that is perfect in-sample has memorised the noise.

Five Questions for Monday

  • Which of our categories respond to temperature, and have we tested for a threshold and asymmetry, not just a single slope?
  • Do our forecast reports show bias, by month and temperature band, next to MAPE?
  • Is safety stock calibrated on seasonal σ measured over the full review-plus-lead-time window, or on one annual number?
  • Do we archive the weather forecasts we used, and do we know their error by horizon for our locations?
  • If a new model beats ours on MAPE, how does it behave on days hotter than anything in its training data?

Demand in temperature-sensitive categories is not random. It is reading the weather forecast. The only question is whether your planning system reads it too.


Originally published on LinkedIn.

Рубрика: English articles | Оставить комментарий

Как построить цифрового единорога в раздробленной грузовой логистике: уроки Sennder

Европейский рынок автомобильных грузоперевозок — один из крупнейших в мире по объёму и один из наиболее раздробленных по структуре. Десятки тысяч малых перевозчиков, непрозрачное ценообразование, ручные процессы бронирования, отсутствие единого стандарта данных. Именно здесь в 2015 году Дэвид Нотакер и его партнёры основали Sennder — и за десять лет превратили компанию в ведущего цифрового экспедитора в Европе с 1 000 сотрудников в 11 офисах и более чем 12 500 подключёнными грузовиками.

Интервью #188 подкаста Alcott Global — один из немногих случаев, когда основатель реального единорога в логистике рассказывает не о том, что получилось, а о том, как именно принимались решения на каждом повороте. Не маркетинговая история успеха, а разговор о структуре отрасли, логике платформенного бизнеса и о том, почему правильный человек важнее любой технологии.

Раздробленность как бизнес-возможность

Есть отрасли, которые технологии уже изменили. И есть отрасли, которые пока сопротивляются — не потому что изменения невозможны, а потому что структура слишком сложная, игроков слишком много, а каждый работает по своим правилам.

Европейский автомобильный фрахт — именно такая отрасль. Подавляющее большинство перевозчиков — это компании с парком до 20 грузовиков. Они не имеют доступа к крупным корпоративным клиентам напрямую: слишком мала надёжность, слишком высоки трансакционные издержки для грузоотправителя. С другой стороны, крупный грузоотправитель не может работать с сотнями мелких перевозчиков индивидуально: нет единого интерфейса, нет гарантии уровня сервиса, нет прозрачности цены.

Нотакер увидел в этом разрыве не проблему рынка, а его архитектурный изъян, который можно исправить. Платформа Sennder выступает посредником нового типа: она агрегирует спрос со стороны грузоотправителей и мощности со стороны перевозчиков, стандартизирует условия, обеспечивает прозрачность ценообразования в режиме реального времени и берёт на себя операционную ответственность за исполнение. Малый перевозчик получает стабильный поток заказов без необходимости выстраивать собственные продажи. Грузоотправитель получает доступ к широкой сети мощностей через единое окно.

Логика проста — но реализация потребовала десяти лет, $350 млн инвестиций и нескольких радикальных разворотов в бизнес-модели.

Путь от консультанта к основателю

Нотакер начинал в Roland Berger — одной из ведущих европейских стратегических консультационных фирм. Это стандартный старт для людей, которые хотят понять, как работает бизнес в самых разных отраслях, прежде чем выбрать свою. Консультинг даёт структуру мышления и насмотренность. Но он не даёт права на ошибку — ты всегда работаешь с чужими деньгами и несёшь рекомендательную, а не операционную ответственность.

Именно ощущение дистанции от реального результата, по словам Нотакера, подтолкнуло его к предпринимательству. Ещё до MBA в INSEAD он основал первую компанию — Smiling Box. Когда она не выстрелила, он не остановился: во время учёбы в INSEAD нашёл партнёров из Roland Berger — Николауса Шефенакера и Юлиуса Кёлера — и в 2015 году запустил Sennder.

Первоначальная модель менялась. Рынок, как всегда, оказался не таким, каким выглядел в презентации. Но основатели удержались: не за идею, а за проблему, которую хотели решить. Это принципиальное различие — компании, влюблённые в идею, умирают, когда идея не работает. Компании, влюблённые в проблему, находят другую идею и продолжают.

Малый перевозчик в эпоху цифровизации

Один из самых практичных тезисов разговора — о судьбе небольших транспортных компаний. Нотакера прямо спрашивают: что делать перевозчику с парком 5–20 грузовиков, чтобы подготовиться к следующим нескольким годам?

Ответ неудобный. Перевозчики этого масштаба не могут позволить себе собственную IT-систему — слишком дорого. Они не могут обслуживать крупных клиентов напрямую — слишком мало надёжности в глазах корпоративного логиста. Они застревают в модели, которая работала, когда рынок был непрозрачным: если все цены скрыты и никто не знает реального уровня сервиса, можно конкурировать за счёт личных связей и локальной известности.

Цифровые платформы разрушают эту непрозрачность. Цены становятся видимы. Репутация измеряется в данных, а не в рукопожатиях. Малый перевозчик, работающий вне цифровой экосистемы, постепенно оказывается в зоне, куда лучшие заказы перестают поступать.

Нотакер говорит об этом без лишнего драматизма, но чётко: интеграция в платформу — не опция, а вопрос времени. Чем раньше перевозчик начинает работать с цифровыми инструментами, тем выше его позиция внутри экосистемы к тому моменту, когда она станет единственным реальным каналом доступа к заказам.

Электромобили и автономность: реализм вместо прогнозов

Вопрос об автономных грузовиках и электрификации — обязательный в любом разговоре о будущем логистики. Нотакер отвечает на него без рекламных формулировок.

Электрические грузовики уже работают на коротких маршрутах и в городской доставке. Экономика там складывается. Для дальнемагистральных перевозок — другая история: инфраструктура зарядки, дальность хода, время простоя при зарядке пока делают электрику неконкурентоспособной на большинстве европейских маршрутов.

Автономные грузовики дальнего следования — горизонт в лучшем случае десяти-пятнадцати лет. Не потому что технология не развивается, а потому что регуляторная среда, страховые модели и общественное доверие не поспевают за лабораторными достижениями. Нотакер советует не ориентироваться на заголовки и не принимать стратегических решений на основе прогнозов с пятилетним горизонтом в этой теме. Разумная стратегия — гибкость: смешанные парки, контракты без жёсткой привязки к технологии, цифровой учёт, позволяющий перестроиться.

Люди важнее технологий

Это, пожалуй, самый важный тезис всего разговора — и наименее ожидаемый от сооснователя технологической компании.

Нотакер говорит прямо: самое важное, что он понял за годы строительства Sennder, — это то, что технология создаётся людьми. Привлечение правильного человека важнее любого конкретного инженерного решения, потому что именно этот человек напишет следующее решение. И ещё одно — и ещё одно.

Это не новая мысль. Но в контексте логистической платформы, которая конкурирует с традиционными операторами по ценовой эффективности, она звучит иначе. Соблазн автоматизировать всё, что движется, и минимизировать человеческий фактор очень велик. Нотакер сопротивляется этому соблазну — и утверждает, что именно качество команды, а не алгоритма, определяет, на какой скорости платформа способна развиваться и адаптироваться.

В найме руководителей он настаивает на трёх принципах. Первый — вкладывать в процесс личное время: CEO не может делегировать найм ключевых людей полностью. Второй — прозрачность с самого начала: максимальная открытость об ожиданиях, культуре, сложностях. Третий — симметрия: «Мы открываемся настолько, насколько можем, и ожидаем того же в ответ. Только на этом строится доверие».

Доверие как конкурентное преимущество

Всё бизнес-модель Sennder держится на доверии. Это не риторика — это операционная реальность. Грузоотправитель доверяет платформе выбор перевозчика. Перевозчик доверяет платформе честность условий и своевременность оплаты. Платформа доверяет и тем и другим достаточно, чтобы брать на себя ответственность за исполнение.

В традиционном экспедировании доверие строилось через личные отношения и репутацию на локальном рынке. Это работало в непрозрачной среде, где альтернативной информации не было. Цифровая платформа делает рынок прозрачным — и одновременно переносит основание доверия. Теперь оно строится через данные: рейтинги, история исполнения, прозрачность ценообразования, скорость реакции на инциденты.

Нотакер строил это доверие сознательно — не как маркетинговый нарратив, а как операционный актив. Перевозчик, которому платят вовремя и по честной цене, не уходит к конкуренту при первой возможности. Грузоотправитель, который получает предсказуемый уровень сервиса, не переключается на следующую платформу при незначительном ценовом преимуществе.

В отрасли с тысячами игроков и низкими барьерами входа устойчивость достигается не технологией, а накопленным доверием. Технологию можно скопировать. Репутацию — нельзя.

Предпринимательская логика, применимая за пределами стартапов

Разговор с Нотакером интересен не только для тех, кто строит логистические платформы. Логика, которую он описывает, применима шире.

Большинство отраслей с высокой фрагментацией и непрозрачным ценообразованием — это потенциальные платформенные рынки. Закупки у малых поставщиков, распределённое производство, региональные сети дистрибуции — везде, где существует разрыв между стороной спроса и стороной предложения, который не закрыт стандартизированным интерфейсом, есть возможность для агрегации.

Вопрос в том, кто её заметит первым — и наберёт команду, способную её реализовать. Нотакер убеждён, что второе важнее первого. Идеи конечны. Способность строить — нет.

Рубрика: Логистические операции | Оставить комментарий

The Illusion of the Optimal Network

What the Model Was Actually Doing

Network design optimization is a well-specified mathematical problem. In its standard form, it's a Mixed Integer Linear Program:

min Σ f_j · y_j + Σ c_ij · x_ij

Subject to:

  • Demand coverage: Σ_j x_ij ≥ d_i for all demand points i
  • Capacity: Σ_i x_ij ≤ cap_j · y_j for all facilities j
  • Binary: y_j ∈ {0,1} — a facility either exists or it doesn't

Where f_j is the fixed cost of operating facility j, c_ij is the cost of serving demand point i from facility j, and d_i is the demand at point i.

The model finds the configuration that minimizes cost — given f_j, c_ij, and d_i as inputs.

This is where the problem starts. Every single input is treated as a known constant.


The Constants That Aren't

Consider a company running its distribution through a 3PL provider — full outsource, 100% of volume. Leadership decides to evaluate bringing part of the network in-house: owned regional hubs that consolidate upstream supply and handle last-mile directly, with the 3PL managing the residual.

The MILP covers twelve scenarios, varying the share of volume through owned nodes from 5% to 80%. At the extremes:

  • Low consolidation (5–20%): total cost higher than the pure 3PL baseline. Not viable.
  • Medium consolidation (35–55%): near cost parity.
  • High consolidation (60–80%): best-case savings of ~3% on a $35–40M annual logistics cost base — roughly $1.0–1.2M per year.

That's a real number. But it's the answer to the wrong question.

The right question is: what happens when the 3PL learns you're moving 60% of volume away from them?


The Parameter That Changes Everything

When you move 60% of volume in-house, the 3PL faces a choice: hold their tariff structure on 40% of remaining volume, or reprice to protect margin on a smaller base.

Run three scenarios: 3PL raises rates on residual volume by 10%, 15%, 20%. The ranking restructures entirely.

No tariff change: High consolidation (60–80%) wins. Saves $1.0–1.2M annually.

3PL raises rates 15% on residual: Medium consolidation (35–55%) — which looked like near-parity at baseline — becomes the actual winner. The "optimal" high-consolidation scenario loses most of its advantage to escalating residual cost.

3PL raises rates 20%: All scenarios above 35% consolidation look roughly equivalent. The ranking from the deterministic MILP is no longer meaningful.

One uncertain parameter — one plausible reaction from a counterparty — and the optimal answer changes entirely.

This is not a modeling failure. This is what happens when you solve a deterministic model over a stochastic problem.


The Formal Problem With Deterministic Optimization

MIT's supply chain network design curriculum distinguishes two approaches:

Deterministic optimization solves:

min TC(x, θ̄)

where θ̄ is a single fixed parameter vector — demand, costs, capacities — representing the expected state of the world.

Stochastic optimization solves:

min E_ξ[TC(x, ξ)]

where ξ is a random variable representing the true state of the world, and the expectation is taken over its distribution.

These are not equivalent. Two measures quantify the gap:

EVPI = min_x E_ξ[TC(x, ξ)] − E_ξ[TC(x*(ξ), ξ)]

EVPI — the Expected Value of Perfect Information — is the benefit you would gain if you somehow knew which scenario would materialise before making your network decision. Since perfect foresight can only help, EVPI ≥ 0. In networks with multiple interdependent nodes and external supplier behaviour, it is not small.

The more practically relevant measure is VSS — the Value of the Stochastic Solution:

VSS = E_ξ[TC(x̅(θ̅), ξ)] − min_x E_ξ[TC(x, ξ)]

where x̅(θ̅) is the solution to the deterministic model under expected-case parameters. VSS is the cost of pretending uncertainty doesn’t exist — the gap between what you pay when you run the deterministic model and implement its answer, versus what you pay when you model uncertainty explicitly. It is always ≥ 0.

The deterministic model gives you the optimal solution for a world that doesn't exist. The stochastic model gives you the best solution for the world that actually will.


What Simulation Adds That Optimization Misses

Instead of solving for the global optimum, the right approach shifts the question:

Not: What is the minimum-cost configuration?
But: Which configuration performs best across the full distribution of scenarios we might face?

This is a different problem. You're not minimizing cost — you're minimizing regret. The metric stops being E[cost] and becomes something like:

Minimax Regret: min_x max_ξ [TC(x, ξ) − TC(x*(ξ), ξ)]

Or in practical terms: which network configuration has the lowest P90 cost? Which configuration loses least when your assumptions are wrong?

In the example above, the scenario analysis covers:

  • 12 network configurations (varying hub count and consolidation share)
  • 3 tariff escalation scenarios on residual 3PL volume (10%, 15%, 20%) — 36 model runs in total
  • Greenfield analysis: optimal network from scratch, testing configurations from 10 to 35 nodes

The Greenfield analysis produced an important finding: the mathematically optimal configuration required 35 nodes. But the cost difference between 20 nodes and 35 nodes was negligible beyond a threshold. There was no meaningful economic argument for the last 15 nodes. The optimization said "35." The scenario analysis said "stop at 20 and revisit."


Why Networks Built on Deterministic Optimization Become Fragile

The real cost of the deterministic approach isn't visible at implementation. It shows up two years later.

A network designed to minimize cost at one demand level and one tariff structure performs well in the scenario it was designed for. When actual demand deviates, when a key provider changes pricing, when a geopolitical event reroutes flows — the network has no resilience built in. Every departure from the design scenario becomes an exception that costs money to manage.

The supply chains I've seen fail under stress were almost always optimized, not robustified. They were efficient in the expected case and brittle in every other case.

The supply chains that held during disruption — sanctions, border closures, provider failures — were usually the ones designed with scenarios explicitly in mind: multiple sourcing options embedded, consolidation decisions made at a level where switching was still possible, provider dependencies managed as a risk variable rather than a cost variable.

Resilience is not a property you add to a network. It's a property you design in — or forfeit at the beginning.


The Practical Implication for Network Design Decisions

The shift I'd argue for isn't abandoning optimization. MILP is the right tool for what it's built for: finding the minimum-cost configuration given a parameter set. Run it. Run it across all twelve configurations and all three tariff scenarios.

What changes is what you do with the output:

  1. Don't pick the scenario that wins on the baseline. Pick the one with the best distribution of outcomes across scenarios — lowest worst-case regret (the minimax criterion), not lowest average cost. Minimizing average regret and minimizing average cost are mathematically identical; the meaningful distinction is between optimizing the expected outcome versus protecting against the worst-case outcome.
  2. Model the behavior of your counterparties, not just your own costs. In network decisions involving external providers, their response to your decision is itself a stochastic variable. Include it.
  3. Design for reversibility. The configurations that allow for phased deployment — start with 20 nodes, expand to 35 if economics hold — dominate configurations that require full commitment upfront. Optionality has value in network design exactly as it does in financial instruments.
  4. Set explicit review triggers. Not a fixed rollout plan, but a decision tree: if consolidation exceeds X% and tariff escalation exceeds Y%, move to next configuration phase. The roadmap is conditional, not linear.

The right answer in this example isn't high consolidation or low consolidation — it's medium consolidation with a phased expansion path: quick wins on existing network rebalancing, a starter hub configuration, a formal decision gate at 12 months — with explicit conditions that trigger or prevent the next phase.

Not an optimal network. A network designed to stay good across a range of futures.


A Note on the Digital Twin

The scenario approach only becomes tractable when the model is calibrated against actual operational data — real transport legs, real handling rates, real demand patterns. A digital twin built on a full year of shipment history turns "run 12 configurations × 3 tariff scenarios" from a research project into an afternoon. The upfront investment is in building the twin. The insight generation scales almost for free.

The failure mode I see most often in network design projects isn't a bad model. It's a good model used to answer one question instead of twelve. The model gets built, the optimal answer gets reported, and the decision gets made — without ever asking what that answer looks like when one key assumption is wrong.

Build the twin. Run the scenarios. Then decide which network you want to operate.


The example is illustrative, constructed to reflect the structure of real network design decisions across multi-cluster QSR and retail distribution contexts. The framework for stochastic network optimization draws on coursework from the MITx MicroMasters in Supply Chain Management.


Originally published on LinkedIn.

Рубрика: English articles | Оставить комментарий

The Question Nobody Asks Before a Collab Launch

The Two Errors Nobody Prices

Every procurement decision under demand uncertainty involves two possible mistakes.

Underage: you ordered less than demand. You run out during the campaign window. Lost sales, disappointed customers, a marketing team that spent budget on awareness for a product people couldn't find.

Overage: you ordered more than demand. The campaign ends. You're sitting on licensed inventory that has a hard shelf life — not because the product expires, but because the license does.

The cost of underage (Cu) is the margin you didn't capture plus the brand effect of the stockout. The cost of overage (Co) is the purchase price minus whatever you can recover — the salvage value.

For most standard products, both errors are painful but roughly comparable. For promotional collab launches, they are not. The overage cost is structurally higher, for one simple reason: licensed packaging has near-zero salvage value after the campaign ends.

You can't sell a co-branded product after the IP window closes. You can't repurpose the packaging. What you have is inventory that is worth either its raw material value or nothing at all.


The Formula That Changes the Answer

The newsvendor model (from inventory theory) gives the optimal order quantity under demand uncertainty:

Q* = F⁻¹(Cu / (Cu + Co))

Where F⁻¹ is the inverse of the demand distribution — the percentile of demand you should target. The ratio Cu/(Cu + Co) is called the critical ratio.

What this says: the optimal order is not the expected (mean) demand. It's a specific percentile of the demand distribution, determined entirely by the relative cost of the two errors.

If Cu >> Co — ordering too few is much more expensive than ordering too many — you should order above the median. Bias toward coverage.

If Co >> Cu — overage is more expensive — you should order below the median. Bias toward conservation.

For most promotional launches, Co is high (salvage ≈ 0) and Cu is moderate (the margin on a limited-edition item matters, but a stockout is not catastrophic to the core business). The critical ratio lands below 0.5. The model says: order less than you expect to sell.

This feels wrong. It isn't.


A Worked Example

Imagine a food chain launching a collab product — a limited-edition item tied to a licensed IP, running for 10 weeks across 400 locations.

Demand forecast: 500 units per location. Standard deviation: 150 units (high uncertainty — no sales history, new IP).

Cost structure:

  • Purchase price: $4.20/unit
  • Selling price: $6.50/unit
  • Margin (Cu per unit): $2.30
  • Salvage value after campaign: $0.40/unit (raw material recovery only)
  • Co per unit: $4.20 − $0.40 = $3.80

Critical ratio: Cu / (Cu + Co) = 2.30 / (2.30 + 3.80) = 0.377

Optimal order quantity: the 37.7th percentile of a normal distribution with mean 500 and σ = 150.

Q* = 500 + (−0.312) × 150 ≈ 453 units per location

Not 500. Not "what marketing forecasted." 453 — because overage is 1.65× more expensive than underage in this structure.

At Q=500 (mean demand), the expected leftover is not zero — it’s approximately 60 units per location, because about half of all scenarios produce a shortfall and half produce a surplus, and the surplus side is uncapped. At $3.80 per unsold unit across 400 locations, the expected write-off from ordering the forecast is ~$91K per launch. The optimal order of 453 reduces expected leftover to ~39 units per location — a write-off of ~$60K. Lost sales rise by ~$24K, so the net gain is ~$7K per launch — small here, but it grows fast as uncertainty rises or salvage value falls.


The Buy-Back Shift

Here is where the structure of the supplier contract changes everything.

Some suppliers — particularly in packaged goods categories where the supplier is also the IP holder or the manufacturer — offer buy-back arrangements: they will repurchase unsold units at the end of the campaign at an agreed price.

Say the supplier agrees to a buy-back at $2.80/unit (67% of purchase price).

Co now becomes: $4.20 − $2.80 = $1.40 per unit (instead of $3.80).

New critical ratio: 2.30 / (2.30 + 1.40) = 0.622

New Q*: 500 + (0.310) × 150 ≈ 547 units per location

The optimal order just jumped from 453 to 547 — a 21% increase — because one clause in the contract restructured the cost of being wrong.

The buy-back doesn't eliminate overage. It caps it. And that changes how aggressively you should commit.

This is why buy-back contracts are not just a risk-sharing tool. They are a demand signal: a supplier willing to offer buy-back is effectively saying "I have more confidence in this product than the current pricing reflects." It's worth reading it that way.


Not All Collabs Are the Same Cu/Co

The newsvendor model reveals something that gets flattened in most launch planning: different collaboration types have structurally different cost profiles, and therefore different optimal order quantities — even at identical demand forecasts.

A collab tied to a long-running IP with high baseline recognition has a different salvage curve than one tied to a trend-driven cultural moment with a hard expiration date. The first may have residual demand after the campaign window; the product can move through clearance without the IP value collapsing. The second has no tail. The license ends, the cultural moment passes, and the inventory becomes a write-down.

Same sales forecast. Same unit economics. Different optimal Q*.

A useful framework before signing a purchase order:

Type A — Evergreen IP, flexible window: Salvage value moderate, campaign end date soft. Co is manageable. Order at or above median demand.

Type B — Trend-driven IP, hard license expiry: Salvage near zero after date. Co is high. Order conservatively — at the 30th to 40th percentile of demand, not the forecast mean. The worked example (CR = 0.377) lands squarely here. Negotiate buy-back aggressively: even partial salvage recovery meaningfully raises CR and shifts the optimal quantity upward.

Type C — Own IP or no license constraint: Residual inventory is a standard markdowns problem, not a write-off. Standard continuous review applies.

Running all three through the same ordering logic is a systematic error that compounds across a portfolio of launches.


What This Means Before the Next Launch

The newsvendor model doesn't require a statistics degree to apply. It requires two numbers that procurement should be able to estimate for any collab: the cost of running out and the cost of being stuck.

Before signing the purchase order:

1. Estimate the critical ratio explicitly. What is the margin on each unit sold? What is the effective cost of each unit left over, accounting for salvage? The ratio of those two numbers determines the percentile of demand you should target — not the mean.

2. Separate demand uncertainty from cost structure. A high-confidence demand forecast still needs the right order percentile. A buy-back contract matters more when demand variance is high.

3. Treat the buy-back negotiation as a separate value lever. A buy-back at 60% of purchase price on a zero-salvage product is worth more than a 3% reduction in unit price. Price it that way.

4. Set an explicit write-off threshold before the launch. If ending inventory above X units triggers a write-down that makes the launch NPV-negative, that threshold is the exit criterion — and it should be agreed before the product ships, not discovered after.

The math doesn't eliminate uncertainty. It structures how you carry it.

Most promotional launches are decided on the forecast. The forecast is the least important input in the model.


Originally published on LinkedIn.

Рубрика: English articles | Оставить комментарий

Почему самый дешёвый поставщик может оказаться дорогим решением

English version: read in English

Есть вопрос, который я задаю каждый раз, когда мне показывают отчёт о сокращении затрат в закупках: «Логистику в эту цифру включили?»

Почти всегда — нет.

Закупочная функция оптимизирует закупочную цену. Логистическая функция оптимизирует стоимость доставки. А где-то в пространстве между двумя этими бюджетами тихо исчезают значительные деньги — не потому что кто-то сделал что-то не так, а потому что обе функции смотрят на разные части одного уравнения.

Проблема оптимизации одной переменной

Дизайн цепочки поставок — это задача минимизации. Полные затраты на операцию сети состоят из трёх составляющих:

Общие затраты = Транспорт + Фиксированные затраты на объекты + Затраты на хранение запасов

Формально: TC = Σ c_ij · x_ij + Σ f_j · y_j + Σ h_j · I_j

где c_ij — удельная стоимость перемещения продукта от поставщика j до узла i, f_j — фиксированная стоимость работы объекта j, h_j — затраты на хранение запасов в узле j.

Большинство закупочных команд минимизируют одно слагаемое: закупочную цену, которая входит как компонент в c_ij. Большинство логистических команд минимизируют другое: тариф за километр. Ни те, ни другие не ошибаются. Обе команды решают часть задачи — пока суммарные затраты растут.

Это расхождение становится дорогостоящим там, где вступает в игру география.


Разбор на примере: задача двух поставщиков

Представьте сеть общественного питания, работающую по всей большой стране — 1 200 точек доставки, распределённых по двенадцати часовым поясам. Компания закупает ключевой ингредиент (назовём его Ингредиент А) у двух федеральных поставщиков вблизи столицы, которые поставляют продукт в центральный распределительный центр. Далее продукт перемещается на 17 региональных кросс-докинговых хабов, а оттуда — в рестораны.

Логистическая цепочка для каждого килограмма Ингредиента А выглядит так:

Поставщик (столичный регион) → Центральный РЦ → Региональный кросс-докинговый хаб → Ресторан

Каждый участок цепи имеет свою стоимость:

  • Межфилиальное перемещение: $0,18/кг
  • Обработка на центральном РЦ: $0,09/кг
  • Дальнемагистральная перевозка до регионального хаба: $0,10–$0,42/кг (в зависимости от расстояния)
  • Последняя миля (~$0,15/кг): фиксирована вне зависимости от расположения поставщика

Теперь вводим регионального альтернативного поставщика — расположенного в 90 км от хаба вместо 3 200 км от столицы. Закупочная цена идентична.

Изменение логистических затрат:

  • Исключение межфилиального перемещения: −$0,18/кг
  • Исключение обработки на центральном РЦ: −$0,09/кг
  • Исключение дальнемагистральной доставки из столицы: −$0,31/кг
  • Добавление короткого плеча от регионального поставщика: +$0,04/кг
  • Последняя миля: без изменений

Чистая экономия на логистике: $0,54/кг. На 400 тоннах в месяц через один хаб — это $216 000 в год. С одного узла. По одному ингредиенту. При одинаковой закупочной цене.

Умножьте на 8 хабов с аналогичной географией и сопоставимыми объёмами — цифра становится существенной.


Почему математика нелинейна

Здесь начинается контринтуитивная часть. Экономия не пропорциональна расстоянию. Она подчиняется структуре, которую в моделях сетей цепочки поставок называют компромиссом задачи размещения объектов.

В классической постановке вы ищете оптимальное размещение объектов снабжения — или в данном случае, регионов закупок — чтобы минимизировать суммарные приведённые затраты. Задача формулируется как задача смешанного целочисленного линейного программирования (MILP):

минимизировать: Σ_j f_j · y_j + Σ_i Σ_j c_ij · x_ij

при условиях:

  • Каждый узел i должен быть обеспечен: Σ_j x_ij ≥ D_i
  • Поставщик j может обслуживать узел только если он активен: x_ij ≤ M · y_j
  • y_j ∈ {0,1} (бинарная переменная: поставщик либо включён, либо нет)

Ключевой вывод модели: по мере добавления региональных точек закупки транспортные затраты поначалу резко снижаются (вы устраняете самые длинные маршруты), а затем выходят на плато (новые поставщики добавляются там, где плечо и так было коротким). Одновременно затраты на управление закупками — квалификация поставщиков, страховые запасы, административный ресурс — растут примерно линейно с числом активных поставщиков.

Оптимальная точка — не «как можно больше региональных поставщиков». Это перегиб, где предельная экономия на логистике начинает уступать предельным накладным расходам на закупки.

В приведённом примере этот перегиб наступил в районе соотношения 60/40 (федеральные/региональные): достаточно регионального объёма, чтобы захватить основную логистическую экономию — но не настолько много, чтобы гоняться за маргинальными выигрышами ценой высоких координационных затрат.


Четыре сценария

Прогон модели по 17 кросс-докинговым узлам — с использованием реальных транспортных тарифов и объёмов — даёт четыре сценария в зависимости от глубины регионализации:

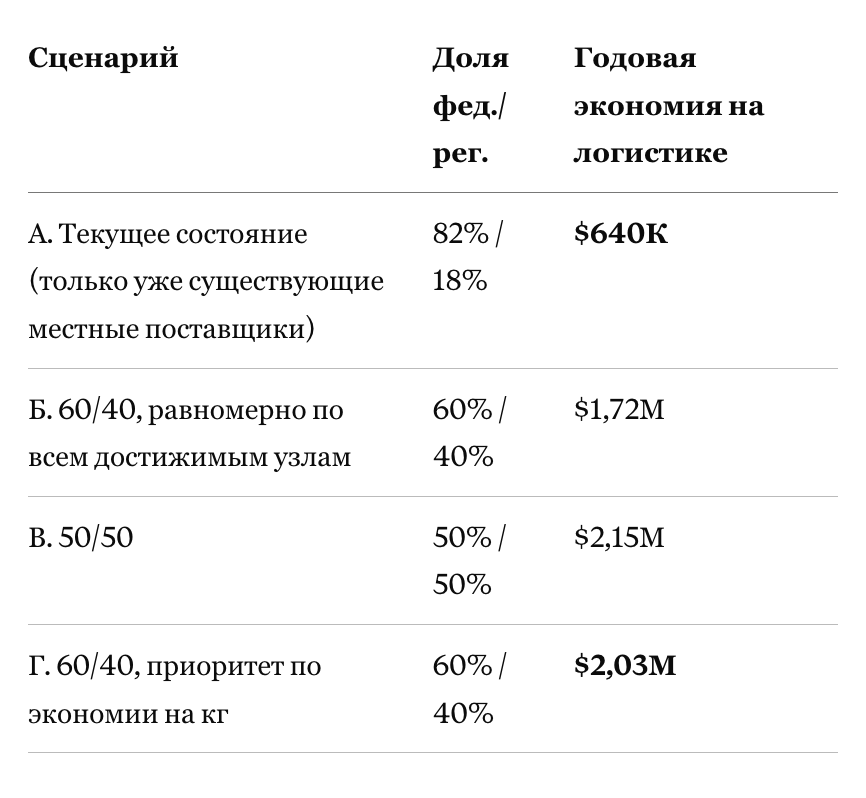
Сценарий Г — практический оптимум. Он достигает той же доли регионального объёма, что и Сценарий Б, но концентрирует этот объём на узлах с максимальной экономией на кг — отдалённых хабах, где доминируют затраты на дальнемагистральную доставку. Результат: на $310К в год больше, чем при «равномерном распределении», при одинаковом числе поставщиков.

Это та же логика плотности из маршрутной оптимизации, применённая к географии закупок: равномерное распределение никогда не оптимально. Концентрация на высокоценных узлах всегда превосходит усреднение.


Ограничение, которое никто не моделирует

Вот чего математика не учитывает: наличие поставщиков.

Модель говорит: нужны региональные поставщики рядом с сибирскими хабами. На карте — три потенциальных кандидата. Двое производят не тот формат продукта. Один существует только на бумаге — это брокер, а не производитель.

На практике Сценарий А (18% региональных, $640К экономии) — это то, что можно начать уже сегодня, потому что поставщики существуют и квалифицированы. Сценарий Г ($2,03М экономии) требует 12–18 месяцев развития поставщиков: аудиты производств, валидация качества, пробные поставки, договоры о резервировании, минимальные объёмы двойного источника для сохранения рычага над федеральным поставщиком.

Именно в этом разрыве — между оптимумом модели и операционной реальностью — буксует большинство программ регионализации. Экономика понятна. Проблема — в последовательности действий.

Практический подход: трёхуровневое развёртывание:

Уровень 1 — Действуем сейчас (поставщики квалифицированы, экономика сильная): Узлы, где региональные поставщики уже есть в радиусе 200 км. Запускаем в IV квартале. Сохраняем ≥20% федерального резерва для поддержания альтернативности.

Уровень 2 — Активно развиваем (сильная экономика, поставщика пока нет): Узлы, где экономия на кг превышает $0,35, но квалифицированного местного источника нет. Это обоснование для активного поиска поставщиков — нужно отправить туда специалиста по закупкам, а не ценовой запрос.

Уровень 3 — Оставляем как есть: Узлы, где экономия на кг ниже $0,15. Накладные расходы на квалификацию регионального поставщика превышают логистический выигрыш. Сохраняем федеральные закупки, оптимизируем условия контрактов.


Второй порядок эффектов

Есть аргумент, который редко попадает в бизнес-кейс по регионализации — но должен.

Когда поставщик знает, что 80% объёма покупателя безальтернативно, он ведёт переговоры соответственно. Развитие регионального поставщика меняет это. Квалифицированная альтернатива в данной географии переводит федерального поставщика из статуса «единственного источника» в статус «предпочтительного источника». Динамика переговоров меняется — ещё до того, как вы переместили хотя бы один килограмм.

Это эффект переговорного рычага: развитие регионального поставщика — это одновременно ценовой сигнал федеральному поставщику. Часть суммарного снижения затрат в Сценарии Г возникает не из логистической экономии, а из улучшения закупочной цены на те 60%, которые остаются у федерального поставщика.

Модель этого не учитывает. Это должно входить в каждый анализ TCO (совокупной стоимости владения).


География — это затраты

Есть соблазн думать о географии поставщиков как о данности: поставщики там, где они есть, и ничего с этим не поделаешь. Но в сетевых моделях цепочки поставок география — это не ограничение, а переменная проектирования.

Когда все поставщики сконцентрированы в одном городе, а спрос распределён по всей стране, вы платите налог на расстояние за каждый килограмм, который перемещаете. Алгоритм маршрутизации это не исправит. Оптимизатор частоты поставок это не исправит. Единственное настоящее решение — географическое перемещение источника. Это закупочное решение в обёртке логистической проблемы.

В моделях транспортных затрат суммарные расходы растут с расстоянием между узлами поставки и спроса нелинейно: сначала быстро, потом медленнее. Именно поэтому первые несколько региональных поставщиков в правильных узлах дают непропорционально большой эффект.

Вопрос в том, рассматриваете ли вы географию как фиксированное ограничение — или как переменную, с которой можно работать.


Я работаю с сетями поставок в разных странах — от рынков с развитой логистической инфраструктурой до тех, где последняя миля непредсказуема. Общая закономерность одна: компании с устойчивым структурным преимуществом по марже — это те, где кто-то в своё время принял решение сдвинуть поставки ближе к спросу. Не полностью. Не равномерно. Но достаточно, чтобы изменить форму кривой затрат.

Это решение редко отражается в отчёте об экономии в закупках. Оно отражается в P&L — два года спустя, как структурное преимущество по марже.

Рубрика: Выбор поставщика | Оставить комментарий

Your Cheapest Supplier Might Be Your Most Expensive Decision

Эта статья на русском: читать по-русски

The Problem With Optimizing One Variable

Supply chain design, at its core, is a minimization problem. The total cost of operating a supply chain network has three components:

Total Cost = Transportation + Fixed Facility Costs + Inventory Holding Costs

Or formally: TC = Σ c_ij · x_ij + Σ f_j · y_j + Σ h_j · I_j

Where c_ij is the unit cost of moving product from supplier j to distribution node i, f_j is the fixed cost of operating facility j, and h_j is the inventory holding cost at node j.

Most procurement teams minimize one term: the purchase price, which shows up as a component inside c_ij. Most logistics teams minimize another: the transportation rate per kilometer. Neither team is wrong. Both teams are solving a part of the problem while the total cost grows.

The place where this gap becomes expensive is geography.


A Worked Example: The Two-Supplier Problem

Imagine a food chain operating across a large country — 1,200 delivery points spread across twelve time zones. The company sources its highest-volume ingredient (let's call it Ingredient A) from two federal suppliers near the capital, who deliver into a central distribution center. From there, product moves to 17 regional cross-docking hubs, then last mile to restaurants.

The logistics structure looks like this for every kilogram of Ingredient A:

Supplier (capital region) → Central DC → Regional cross-dock → Restaurant

Each leg has a cost:

  • Inter-DC transfer: $0.18/kg
  • Central DC handling: $0.09/kg
  • Long-haul transport to regional cross-dock: $0.10–0.42/kg (varies by distance)
  • Last mile (~$0.15/kg): fixed regardless of supplier location

Now introduce a regional alternative — a supplier located 90 km from the Midwest cross-dock instead of 3,200 km away near the capital. Purchase price is identical.

The logistics cost change:

  • Eliminates inter-DC transfer: −$0.18/kg
  • Eliminates central DC handling: −$0.09/kg
  • Eliminates long-haul from capital to Midwest: −$0.31/kg
  • Adds short-haul from regional supplier to cross-dock: +$0.04/kg
  • Last mile: unchanged

Net logistics saving: $0.54/kg. On 400 tons per year through that cross-dock, that's $216,000 per year — from one node, on one ingredient, at identical purchase prices.

Multiply across 8 cross-docks with similar geography and similar volumes, and the number becomes material.


Why the Math Isn't Linear

Here is where it gets counterintuitive. The savings are not proportional to distance. They follow a structure that supply chain network models call the facility location trade-off.

The formal version of this problem is called the facility location model — you're solving for the optimal placement of supply points to minimize total landed cost. The structure is a Mixed Integer Linear Program (MILP):

minimize: Σ_j f_j · y_j + Σ_i Σ_j c_ij · x_ij

subject to:

  • Each node i must be served: Σ_j x_ij ≥ D_i
  • A supplier j can only serve a node if it's active: x_ij ≤ M · y_j
  • y_j ∈ {0,1} (binary: supplier is either in or out)

The insight the model reveals is this: as you add more regional sourcing points, transportation cost falls sharply at first (you're eliminating very long hauls), then flattens (you're adding suppliers in places where the haul was already short). Meanwhile, procurement complexity — qualification costs, safety stock requirements, relationship management — increases roughly linearly with the number of active suppliers.

The optimal point is not "as many regional suppliers as possible." It's the inflection where marginal logistics savings start to fall below marginal procurement overhead.

In the example above, this inflection appeared around a 60/40 split (federal/regional): enough regional volume to capture the largest logistics savings, not so much that you're chasing marginal gains at high coordination cost.


The Four Scenarios

Running the model across the 17 cross-docking nodes — using actual transport tariffs and node volumes — produces four scenarios depending on how aggressively you regionalize:

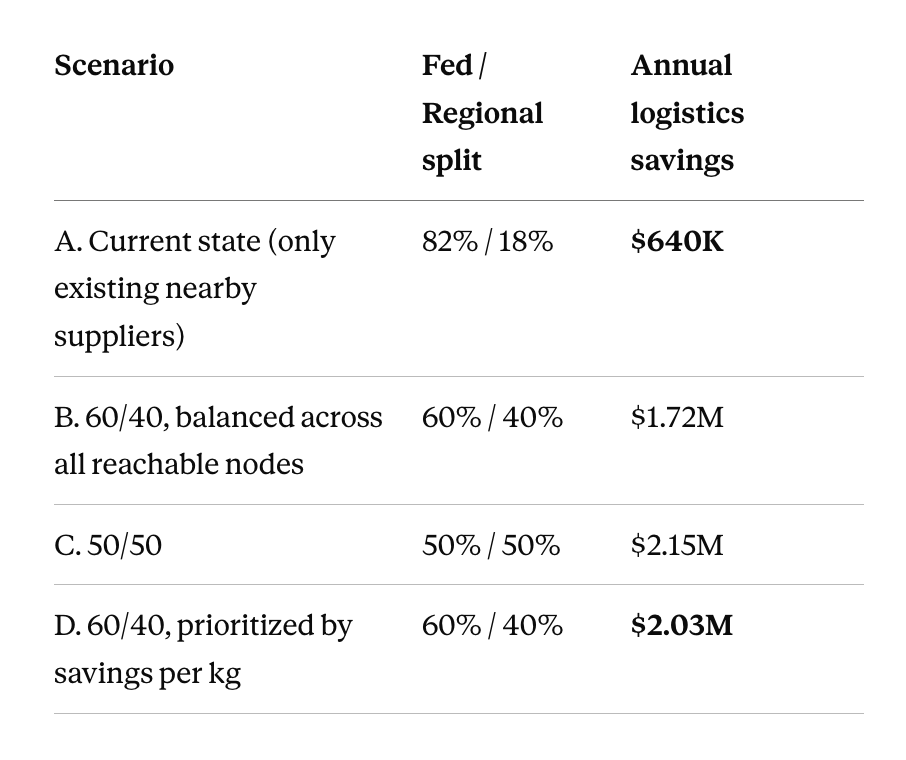
Four regionalization scenarios: share of regional volume vs annual savings

Scenario D is the practical optimum. It achieves the same regional volume share as Scenario B but concentrates that volume at the nodes with the highest per-kg savings — remote cross-docks where long-haul costs dominate. The result: $310K more in annual savings than the "evenly distributed" version at the same supplier count.

Scenario C saves $120K more in gross logistics savings than D, but requires moving 10 percentage points more volume to regional suppliers — additional qualification costs, higher safety stock at regional nodes, and ongoing relationship management overhead. Once that overhead is priced in (typically $130–150K/year for the extra supplier layer), D’s total cost of ownership is lower despite the smaller gross saving. The model optimizes logistics; the right answer optimizes total cost.

This is the stop density logic from route optimization, applied to sourcing geography: uniform distribution is never optimal. Concentration at high-value nodes always outperforms averaging.


The Constraint Nobody Models

Here's what the math cannot capture: supplier availability.

The model says you need regional suppliers near the Siberian cross-docks. The map shows three potential candidates. Two of them produce the wrong product format. One of them exists only in theory — they're a broker, not a manufacturer.

In practice, Scenario A (18% regional, $640K savings) is what you can start today, because the suppliers exist and are qualified. Scenario D ($2.03M savings) requires 12–18 months of supplier development: factory audits, quality validation, trial shipments, contingency agreements, dual sourcing minimums to keep the federal supplier engaged.

This gap — between the model's optimal and the operational reality — is where most regionalization programs stall. The economics are clear. The sequencing is the problem.

The practical approach is a three-tier rollout:

Tier 1 — Act now (suppliers qualified, economics strong): Nodes where regional suppliers already exist within 200 km. Start here in Q4. Run at ≥20% federal backup minimum to maintain optionality.

Tier 2 — Develop actively (economics strong, no supplier yet): Nodes where savings per kg exceed $0.35 but no qualified local source exists. These justify active supplier prospecting — send a procurement person there, not a price inquiry.

Tier 3 — Leave as is: Nodes where savings per kg are under $0.15. The procurement overhead of qualifying a regional supplier exceeds the logistics benefit. Keep federal sourcing, optimize terms instead.


The Second-Order Effect

There's an argument that rarely makes it into the regionalization business case, but probably should.

When a supplier knows that 80% of a buyer's volume is captive — that there's no credible alternative — they negotiate accordingly. Regional supplier development changes that. A qualified alternative in a given geography shifts the federal supplier from "sole source" to "preferred source." The negotiating dynamic changes before you've moved a single kilogram.

This is the sourcing leverage effect: developing a regional supplier is also a price signal to the federal supplier. Some portion of the total cost reduction in Scenario D comes not from logistics savings, but from purchase price improvement on the 60% that stays federal.

The model doesn't capture this. It should be in every TCO (Total Cost of Ownership) analysis.


The Connection to the Previous Problem

In the last article, I wrote about route optimization and the density trap: why sparse geographies cost more per delivery, not linearly, but following a square root relationship, as stop density falls.

Supplier regionalization is the same principle applied one tier upstream. When all your suppliers cluster near one city and your demand is distributed across a continent, you're paying a density tax on every kilogram of product you move. The algorithm can't fix it. The route optimizer can't fix it. The only fix is geographic repositioning of supply — which is a sourcing decision dressed up as a logistics problem.

The math connects: in distribution cost models, distance per stop grows with 1/√δ where δ is stop density. In supply network design, total transportation cost grows with the distance between supply nodes and demand nodes. Both frameworks say the same thing: geography is cost.

The question is whether you're treating it as a fixed constraint or a design variable.


When I think about what well-designed food supply chains look like at regional scale — whether in Central Asia, Southeast Asia, or across Eastern Europe — the common thread isn't sophisticated route optimization software or real-time inventory visibility. It's that someone, at some point, made the deliberate decision to move supply closer to demand. Not all the way. Not uniformly. But enough to change the shape of the cost curve.

That decision usually doesn't show up in a procurement savings report. It shows up in the P&L, two years later, as a structural margin advantage.


Originally published on LinkedIn.

Рубрика: English articles | Оставить комментарий

Why Your Route Optimization Is Failing (And It Has Nothing to Do with the Algorithm)

Before We Talk About Routes, We Need to Talk About the System

Most conversations about route optimization jump straight to the algorithm: VRP, Clarke-Wright, simulated annealing, machine learning. But there's a layer below that almost nobody touches in practice — and skipping it is why most optimization projects either underdeliver or quietly get abandoned.

That layer is the flow of the system itself.

Start with a simple observation. In any process — warehouse, truck fleet, distribution network — three things are always related: the number of items in the system at any given moment, the rate at which items move through it, and the time each item spends inside it. These three aren't independent. Change one and the others change too, mechanically, like a conservation law.

If your warehouse processes 100 shipments per day and each order takes half a day from receipt to dispatch, you will have, on average, roughly 50 orders in process. Not at every moment — at any given point the actual count can be higher or lower depending on arrival patterns and variability — but as a long-run average, this relationship is exact. It’s called Little’s Law (L = λW), and it holds in steady state regardless of the distribution of inter-arrival times or processing times. Want fewer orders in process? Either speed up throughput or shorten the processing time. There's no third option.

This seems obvious. And yet most distribution operations I've seen try to manage inventory and route timing as separate problems — without recognizing that they're expressions of the same underlying constraint.

The second thing that almost always gets missed is the bottleneck. Every system has one stage that limits the output of the whole chain. You can optimize every other stage to perfection; it changes nothing, because the output is capped by the slowest step. In a distribution context, this is often not the truck or the route — it's the loading dock, the dispatch window, or the inventory accuracy that makes loading possible in the first place.

I've seen cases where the routing was designed for 4 trucks and the network genuinely needed 4 trucks — but the warehouse could only load 2 per shift. The route plan was right. The bottleneck was upstream. Two trucks moved, two sat. And no amount of route re-optimization would have fixed it.

The third factor is variability. This one is the most underappreciated. When demand is unpredictable, when supplier lead times are uneven, when the gap between "what the system shows" and "what's physically in the warehouse" fluctuates — the effect on delivery costs is non-linear. Not just "higher on bad days." The relationship between variability and waiting time follows a curve: at low utilization, variability barely matters. As you approach capacity, the same variability causes costs to explode. This is why a distribution network that looks fine on average can generate emergency deliveries constantly — the averages are fine, but the peaks are brutal.


A Worked Example: The Two-City Problem

Imagine a food distribution company. Single depot. Two delivery regions.

Region A is dense: 50 restaurants within 30 km, all ordering daily. Region B is sparse: 20 restaurants spread across 150 km, ordering 3 times a week.

You want to estimate total fleet distance. Not optimize it exactly — just understand the structure of the problem before deciding how much to invest in fixing it.

For any one-to-many distribution network, the total distance across all vehicle tours has two components. The first is linehaul: how many trips from the depot to each region, multiplied by the round-trip distance. The number of trips depends on total demand volume divided by vehicle capacity — if total weekly demand for Region B is 40 pallets and your truck holds 10, you need at least 4 trips.

The second component is local routing inside each region: the distance the truck actually covers driving between stops. This part depends not on demand volume but on stop density — how many delivery points are packed into the area. Dense coverage means short loops. Sparse coverage means long detours between stops.

Here's what this reveals about the two regions. Region A has high density. Each truck trip is short. Linehaul is frequent but cheap per stop. Local routing is efficient. Total cost per delivery: manageable.

Region B has low density. Each truck covers a lot of ground between stops. Even if total demand is lower, the distance per delivery is much higher — not because the linehaul is longer (though it is), but because sparse stops mean inefficient local routes. Add the variability of 3x-per-week ordering patterns instead of daily, and you get inconsistent load factors on top of inefficient routes.

The trap is that most companies look at Region B's lower order volume and assume it's cheaper to serve. It often isn't. The sparse density makes local routing expensive in ways that don't show up in a simple cost-per-kilometer analysis.

And when Region C gets added — even sparser, even further — the economics get worse again, non-linearly. It's not that distance added to the network scales linearly with cost. The density effect compounds.


The Gap Between the Model and Tuesday Morning

Route optimization assumes the inputs are known. Demand at each stop, delivery windows, vehicle availability. The algorithm takes those inputs and finds a good solution.

The problem is that in many real distribution networks, the inputs aren't reliable.

Demand forecasting is informal. Stock counts are manual and sometimes days old. The warehouse team doesn't trust the system, so they plan by instinct. A region runs short on a key ingredient, a truck gets dispatched outside the plan at spot pricing, and the unit economics quietly deteriorate. The algorithm didn't fail — it never got clean data to work with.

Then there's the loading constraint. Routing software schedules routes based on vehicle count and capacity. It doesn't know that your dispatch dock has a 2-truck-per-shift limit. So the system generates a 4-truck plan. Two trucks load. Two wait. Half the routes don't run on time. Drivers learn that the plan is theoretical. They stop following it.

And then there's geographic expansion. Adding a new delivery region feels like adding new stops to the network. But as the earlier example shows, it changes the density of the whole distribution problem — and not in a linear way. What was manageable at 30 stops becomes chaotic at 80, not because the algorithm can't handle it, but because the organizational processes — verification, communication, exception handling — can't keep up.


What Actually Has to Come First

The diagnostic sequence I've come to use starts from the bottom of the stack, not the top.

Before optimizing routes, can you trust your demand data? Not "does a number exist in the system" — but "does the team making loading decisions trust it enough to plan against it?"

Before optimizing routes, is warehouse throughput a binding constraint? If the dispatch dock is the bottleneck, more sophisticated routing doesn't help. Fix the capacity limit first.

Before optimizing routes, do you have delivery confirmation data? Not just shipped — received, verified, timestamped, with responsibility assigned. Without this, the feedback loop that improves future route planning doesn't close.

Only after these three are solid does it make sense to invest seriously in route optimization tooling. The algorithm will do its job. The question is whether the organization can provide the inputs it needs and execute what it produces.


Originally published on LinkedIn.

Рубрика: English articles | Оставить комментарий

Революция функции закупок идёт из Азиатско-Тихоокеанского региона — и она организационная

English version: read in English

Тридцать лет рецепт «правильных закупок» остаётся поразительно неизменным. Централизовать расходы. Внедрить управление категориями. Поставить систему автоматизации от заявки до оплаты. Оцифровать хвост номенклатуры. Нанять директора по закупкам с громким титулом и мандатом на снижение затрат.

Ничего не меняется — потому что базовая организационная модель не изменилась вообще. Закупки по-прежнему — функция внутри иерархии, отчитывающаяся наверх, ответственная за экономию, измеряемая отклонением закупочных цен.

Самый интересный вызов этой модели исходит не от искусственного интеллекта и не от консалтинговых фреймворков. Он исходит из Азиатско-Тихоокеанского региона — и он организационный.

Чжан Жуймин и конец менеджера среднего звена

В 2012 году Чжан Жуймин — основатель и тогдашний генеральный директор Haier — сделал то, о чём теоретики менеджмента спорят по сей день. Он начал демонтировать собственную организацию.

Haier — производитель бытовой техники с оборотом 20 млрд долларов и 80 000 сотрудников — был реорганизован примерно в 4 000 микропредприятий. Каждое работает как независимый бизнес — со своим финансовым результатом, собственным позиционированием на рынке, полномочиями самостоятельно нанимать людей, заключать партнёрства и выстраивать стратегию. Двенадцать уровней менеджмента среднего звена сократились до трёх. Скорость принятия решений выросла на 67%. За следующее десятилетие Haier показал годовой рост 28%, рост прибыли — 1 200% — и стал крупнейшим в мире производителем бытовой техники.

Чжан назвал модель «жэньданьхэи» — термин, сложенный из трёх китайских концептов: жэнь (сотрудник), дань (ценность для пользователя), хэи (единство). Ключевая идея: каждый человек в организации должен находиться в прямой связи с той ценностью, которую он создаёт для клиента. Иерархия между ними — это трение, а не управление.

Для функции закупок следствие радикальное. В структуре «жэньданьхэи» закупки — не централизованная функция, контролирующая расходы от имени бизнеса. Это само по себе микропредприятие, конкурирующее за внутренних клиентов, ответственное за реальное создание ценности и способное привлекать внешних партнёров, если его внутреннее предложение оказывается недостаточно конкурентным. Менеджеры категорий перестают быть контролёрами затрат внутри иерархии. Они становятся предпринимателями с собственным финансовым результатом.

Срединная платформа Alibaba: другая модель

Ответ Haier — радикальная децентрализация. Alibaba пришла к иному решению: не менее азиатскому по логике, но структурно противоположному.

В 2015 году генеральный директор Дэниел Чжан формализовал то, что стало известно как модель «чжунтай» — «срединная платформа». Вместо того чтобы централизовать функции в монолитной организации общего обслуживания, Alibaba выстроила слой общих возможностей — инфраструктура данных, аналитика логистики, сети поставщиков, финансовые сервисы, — которые множество бизнес-единиц потребляют как платформу. Taobao, Tmall, Lazada и десятки других подразделений работают как автономные «фронтальные» структуры, быстро адаптируясь к своим рынкам. Срединная платформа обеспечивает сложность, масштаб и преемственность под ними.

Для закупок логика «чжунтай» означает: централизуй возможность, а не решение. Платформа хранит отношения с поставщиками, экспертизу по категориям, данные о рисках и договорную базу. Бизнес-единицы используют её в своём темпе, не проходя через закупочную иерархию. Функция становится инфраструктурой, а не привратником.

Две азиатско-тихоокеанские модели, две организационные философии — обе превосходящие западный стандарт в виде централизованных закупок с разрозненным управлением категориями.

Почему эти модели появились именно здесь

Невозможно до конца понять «жэньданьхэи» или «чжунтай», не понимая культурного контекста, который сделал их возможными.

Исследования Герта Хофстеде дают отправную точку. Культуры Восточной Азии демонстрируют крайне высокий показатель долгосрочной ориентации — Китай на уровне 87, Япония — 88, Южная Корея — 100. Это определяет логику выстраивания отношений с поставщиками: не как транзакционные контракты, подлежащие перезаключению в каждом цикле, а как долгосрочные инвестиции в совместные возможности. Поставщик в Японии или Корее — это не продавец, которого нужно выжать до максимума, а партнёр, в которого вкладываются. Японская модель кэйрэцу институционализировала это вплоть до структур совместного владения. Samsung и Hyundai выстроили целые экосистемы поставщиков именно так.

Эти же культуры глубоко коллективистские: Китай набирает 20 баллов по шкале индивидуализма, Южная Корея — 18. Коллективная ответственность ощущается естественной; индивидуальный финансовый результат не разрушает командную сплочённость. Именно это позволяет «жэньданьхэи» с её микропредприятиями работать так, как это было бы культурно трудно устойчиво реализовать в Австралии (индивидуализм — 90) или США (91).

Эрин Мейер добавляет поведенческий слой. Её аспект доверия, пожалуй, наиболее принципиален для закупок: большинство стран Азиатско-Тихоокеанского региона строят отношения на личном доверии — оно формируется через прямой контакт, совместно проведённое время и инвестиции в отношения ещё до подписания контракта. Китайский поставщик, который доверяет вам лично, решит вашу проблему в два часа ночи во время кризиса. Тот, у которого есть только подписанное соглашение об уровне сервиса, — возможно, нет.

Не менее важен аспект коммуникации. Высококонтекстные культуры — Япония, Китай, Корея, большинство стран Юго-Восточной Азии — передают смысл имплицитно: через контекст и отношения, а не через прямое высказывание. Контракт по закупкам в Японии несёт иной вес, чем тот же документ в Германии. Он фиксирует скелет договорённости, но не её содержание. Живое понимание существует в отношениях, а не на бумаге.

Есть парадокс в центре всего этого. «Жэньданьхэи» — модель, рождённая в Китае, одной из стран с наибольшей дистанцией власти по Хофстеде. Чжан Жуймин выстраивал её намеренно — как противодействие конфуцианской иерархии, которая иначе окаменила бы его организацию. Это не продукт китайской культуры — это целенаправленная интервенция против одной из её тенденций, ставшая возможной благодаря другой: коллективистской сплочённости, позволяющей небольшим предпринимательским командам самоорганизовываться без той атомизации, которая преследует западные эксперименты с децентрализацией.

Функция закупок в мультикультурной среде

В Dodo Brands функция выстроена по трём чётким направлениям: закупки, снабжение и проекты. Внутри закупок глобальные и региональные команды не дифференцированы иерархически — они ведут одинаковые роли с одинаковым мандатом. Их различает охват категорий, а не принадлежность к уровню. Молочная продукция, упаковка, кофе — категории, где консолидация объёма по всем рынкам создаёт значимый масштаб — управляются глобально: одна команда, несколько кластерных стратегий, все географии. Всё остальное — решение регионов.

Культурная сложность, которую это создаёт, — не противостояние стратегии и исполнения. Это одна и та же функция, выполняющая одну и ту же работу на рынках, занимающих очень разные позиции на культурной карте Мейер. Переговоры с поставщиком, проводимые по одному сценарию в Москве и Дубае, дадут разный результат — не потому что стратегия по категории неверна, а потому что доверие, стиль коммуникации и иерархия работают в этих контекстах по-разному. Функциональная ясность в части владения категориями этого не решает. Она лишь делает культурный разрыв более видимым.

Как посчитать: когда глобальное управление категорией оправдано?

Выбор между глобальным и региональным охватом категории — не вопрос интуиции. Это исчисляемый компромисс между масштабной экономией и координационными издержками, где культурная дистанция выступает ключевой переменной.

Определим чистую ценность глобального управления категорией:

NV_global = ΔS(n) − ΔC(n, D̄)

Где ΔS(n) — приростная экономия от консолидации расходов по n рынкам, а ΔC(n, D̄) — координационные издержки: функция числа рынков n и их средней культурной дистанции от центра закупок, D̄.

Масштабная экономия следует логарифмической кривой — каждый дополнительный рынок вносит меньший вклад, чем предыдущий:

ΔS(n) = α · V · ln(n / n₀)

Координационные издержки масштабируются линейно — больше рынков означает больше циклов согласования, а большая культурная дистанция означает, что каждый цикл потребляет больше времени и капитала отношений:

ΔC(n, D̄) = β · D̄ · n

Глобальное управление категорией оправдано, когда NV_global > 0. Преобразование даёт критический порог расходов V*:

V = β · D̄ · n / (α · ln(n / n₀))*

Категории выше V* генерируют положительную чистую ценность при глобальном управлении. Ниже — региональный подход экономически эффективнее.

Культурная дистанция D̄ измеряется с помощью индекса Когута — Сингха — стандартного количественного показателя в международных бизнес-исследованиях:

CD_hj = (1/4) · Σᵢ [(I_ij − I_ih)² / Vᵢ]

Где I_ij — показатель страны j по измерению Хофстеде i, I_ih — показатель «домашнего» рынка, Vᵢ — дисперсия этого измерения по всей выборке стран. Индекс агрегирует культурный разрыв между двумя рынками по всем четырём измерениям Хофстеде в одно число.

С иллюстративными параметрами: α = 0,03 (3% экономии на каждое удвоение консолидированного объёма), β = 15 000 долларов на рынок в год в виде координационных издержек, n = 25 рынков.

При умеренном культурном разнообразии (D̄ = 1,5):

V = 15 000 × 1,5 × 25 / (0,03 × ln 25) ≈ 5,8 млн долларов*

Категории с годовым консолидированным объёмом выше примерно 6 млн долларов: глобальное управление создаёт чистую ценность. Ниже этого порога — регионы выигрывают экономически.

Эффект культурной дистанции систематически смещает этот порог: чем выше разнообразие рынков, тем выше объёмная планка для глобального управления категорией. Организации с очень неоднородным географическим присутствием нуждаются в значительно большем объёме расходов, чтобы оправдать консолидацию — и они систематически чрезмерно централизуют управление, когда игнорируют эту переменную.

Модель объясняет и обратное: почему низкообъёмные, локально дифференцированные категории противостоят глобальному управлению не только культурно, но и экономически. Координационные издержки превышают масштабную выгоду ещё до учёта качества исполнения. Региональные команды, работающие в собственном культурном контексте, просто достигают большего на каждый рубль организационных усилий.

Именно это Хофстеде квантифицирует, а «жэньданьхэи» операционализирует: культурная дистанция — не мягкий управленческий вызов. Это переменная затрат с точно измеримым влиянием на организационную эффективность. Функция закупок, игнорирующая её, будет хронически неверно распределять права принятия решений.

Что это означает для дизайна функции

Организационная революция, идущая из Азиатско-Тихоокеанского региона, — это не набор моделей для прямого копирования. «Жэньданьхэи», пересаженная в западную организацию без культурного субстрата, породит хаос. «Чжунтай» без информационной инфраструктуры Alibaba останется презентацией.

Азиатско-Тихоокеанский регион предлагает другой набор вопросов.

Что если ответственность в закупках существовала бы на уровне создаваемой ценности — а не на уровне управляемых расходов? Что если функция была бы инфраструктурой, а не контрольным механизмом? Что если организационная модель исходила бы из культуры людей, её реализующих, а не из западного шаблона лучших практик?

И — пожалуй, самое практичное — что если сначала посчитать координационные издержки культурной дистанции, и только потом решать, какие категории управлять глобально?

Компании, задающие эти вопросы всерьёз — Haier, Alibaba, следующее поколение азиатско-тихоокеанских операторов, выстраивающих цепи поставок с чистого листа, — строят функции закупок, не похожие ни на что из учебников.

Это и есть революция, за которой стоит наблюдать.

Рубрика: Технологии | Оставить комментарий

The Inventory Paradox: Why Checking Your Stock Less Often Forces You to Hold More of It

Эта статья на русском: читать по-русски

Most managers intuitively believe that reviewing inventory less frequently saves time and cost. Mathematically, it does the opposite — and the delta compounds across every SKU in your network.


There's a question I ask every procurement or operations manager I work with when we first discuss inventory policies:

"How often do you check your stock levels?"

The answers vary — weekly, twice a week, monthly. Very rarely: daily.

The follow-up question is the one that tends to change the conversation: "Do you know how much that review frequency is costing you in frozen working capital?"

Most don't. And the reason is that the relationship between review frequency and safety stock is non-linear, counterintuitive, and almost never made explicit in the systems that generate replenishment orders.

I first encountered the formal framework for this in Dr. Chris Caplice's inventory management courses at MIT. The mathematics is clean. The practical implication, once you run it against a real network, is anything but small.


Two Policies, One Supply Chain

Inventory theory offers two fundamental approaches to replenishment:

Continuous review — (s, Q) policy
You monitor inventory in real time (or daily). When stock falls to a reorder point s, you trigger an order of fixed quantity Q. The inventory position is checked continuously; the trigger is automatic.

Periodic review — (R, S) policy
You check inventory every R time units (weekly, bi-weekly, monthly). At each review, you order whatever quantity brings you up to a target level S. Between reviews, you don't look — and don't order.

At first glance, periodic review seems simpler and cheaper to operate. You batch the cognitive and administrative work into a fixed cadence. One review per week instead of seven.

The problem is what happens during the interval between reviews.


The Mathematics of Uncertainty Over Time

Safety stock exists to absorb demand variability during the period when you cannot respond. Under continuous review, that period is the lead time L — the gap between placing and receiving an order. If demand spikes unexpectedly, you placed your order at reorder point s, and the goods arrive in L days.

Under periodic review, the exposure window is longer: R + L. If demand spikes the day after a review, you won't notice until the next review R days later, and goods won't arrive until L days after that. You are blind for R days.

The safety stock formula captures this directly:

Continuous review:

SS_c = z × σ_d × √L

Periodic review:

SS_p = z × σ_d × √(R + L)

Where z is the service-level coefficient, σ_d is demand standard deviation per time unit, L is lead time, and R is the review interval.

The ratio between them:

SS_p / SS_c = √((R + L) / L) = √(1 + R/L)

This is the cost of infrequency. When review interval R equals lead time L, periodic review requires 41% more safety stock than continuous. When R is twice L, the premium rises to 73%. The relationship grows with the square root, so it never becomes catastrophic — but it never disappears either.


A QSR Illustration

Let me make this concrete with an abstracted example from a distributed beverage franchise network.

Ingredient A — a temperature-sensitive beverage concentrate delivered to five regional warehouses across different climate zones.

Parameters:

  • Weekly demand forecast: 650 units
  • Demand standard deviation (empirical, weekly): 170 units
  • Lead time: 4 days (0.57 weeks)
  • Target service level: 99.3% → z = 2.44
  • Review interval options: daily (continuous) vs weekly (R = 1 week)

Safety stock calculations:

Safety stock: continuous vs periodic review
Cost of review interval per location

207 units per location. At a unit cost of $1.50, that’s $310 in permanently frozen working capital per SKU per warehouse — capital that generates no revenue, occupies shelf space, and in the case of perishable ingredients, creates write-off risk.

Across 5 locations and 20 temperature-sensitive SKUs:

207 × $1.50 × 5 × 20 = ~$31K tied up in review-interval inventory

Not in safety stock against real demand uncertainty. In safety stock against the fact that you didn't check yesterday.

The Temperature Wrinkle

Standard inventory models assume demand variability is stationary — σ_d doesn't change month to month. For most QSR categories, this is approximately true. For cold beverages, it's demonstrably false.

Empirical analysis of beverage sales across climate zones shows a well-documented asymmetry: demand rises roughly 12–13% per +1°C above a threshold, but falls only 5–6% per −1°C below it. The mechanism is physiological and behavioral — heat triggers impulsive thirst-driven purchasing with no natural ceiling, while cold primarily affects casual traffic without eliminating loyal core demand.

This asymmetry has two implications for policy choice:

First: σ_d is seasonal. Your winter σ_d and summer σ_d are different numbers. A safety stock formula calibrated on annual average demand variability will be systematically under-stocked in July and over-stocked in January.

Second: the value of continuous review is higher in summer. When a heat event hits unexpectedly, continuous review catches the inventory drawdown in real time and triggers a reorder within one review cycle (one day). Periodic review — if you're two days past your weekly check — won't trigger a reorder for five more days. Five days at +12%/°C demand acceleration can exhaust a full week of safety stock.

In practice, this means that the policy choice is not static: a beverage operation that runs periodic review in winter may need to shift to continuous in summer, or build season-specific safety stock tables for each temperature cluster.


The Network Aggregation Problem

One more layer that matters at scale: safety stocks don't aggregate linearly.

If you have five warehouses serving different demand regions, the naive approach is to calculate safety stock per warehouse and sum them. But this overstates the true buffer required by the central stock, because fluctuations across regions are partially independent — when the south runs hot, the north may be cool.

The correct aggregation for independent demand:

σ_total = √(σ₁² + σ₂² + σ₃² + σ₄² + σ₅²)

Not Σσᵢ. For five equal warehouses with σ = 170 each:

  • Naive sum: 5 × 170 = 850 units
  • Correct aggregation: √(5) × 170 = 380 units

The difference — 470 units — is the risk pooling effect of centralised visibility. It is only achievable if you can see all five locations simultaneously and reallocate in real time. Which, again, requires continuous rather than periodic monitoring.


When Each Policy Wins

Neither policy is universally superior. The choice depends on four parameters:

Use continuous (s, Q) when:

  • Items are expensive or perishable (high cost of overstock)
  • Demand is volatile or weather-driven (high σ_d, non-stationary)
  • Your WMS or ERP provides real-time inventory visibility
  • The product's contribution to stockout cost is high

Use periodic (R, S) when:

  • Items are cheap, non-perishable, with stable demand
  • Supplier imposes fixed delivery schedules regardless of order timing
  • IT infrastructure supports only batch-mode stock counting
  • Multiple SKUs can be logically batched in one review cycle

In practice, the real bottleneck is usually operational, not mathematical. The QSR industry historically runs periodic review because physical stock counting was manual. As ERP and WMS systems with real-time scan-in capability became standard, the cost of continuous review dropped to near zero — while the working capital benefit of the shift remained constant.

The question has changed from "can we afford continuous review?" to "do we know what periodic review is costing us?"


The Decision Framework

Before choosing a policy, calculate the cost of infrequency for your highest-value SKUs:

Step 1: Estimate σ_d from historical demand data (separate summer and winter datasets if the category is temperature-sensitive).

Step 2: Calculate SS_p and SS_c for your current lead time and review interval.

Step 3: Multiply delta by unit cost and number of locations.

Step 4: Compare against the operational cost of shifting to daily review.

For most QSR categories, step 4 produces a number close to zero — modern systems review automatically. The delta in step 3 is pure working capital freed.


Closing

The review policy embedded in your replenishment system is one of the most invisible levers in supply chain finance. It doesn't appear in a P&L line. It doesn't generate a variance report. It quietly determines how much working capital is parked in warehouses against uncertainty that your system could be monitoring in real time.

The formula is simple. The implication is not small.

If you're running weekly reviews on temperature-sensitive perishables across a distributed network, you're not just accepting operational simplicity. You're accepting a structural overstock position — and its associated working capital cost — as a permanent feature of how your supply chain works.

It doesn't have to be.


Originally published on LinkedIn.

Рубрика: English articles | Оставить комментарий